


daVinci MagiHuman Text / Image to Video Generator with Audio Sync
Create videos with daVinci MagiHuman - a 15B open-source audio-video foundation model by Sand.ai and SII GAIR Lab. Generate synchronized video and audio from text or images with industry-leading lip sync accuracy across 7 languages. Supports up to 1080p resolution with 5-10 second duration. Powered by a single-stream Transformer architecture with no cross-attention, delivering 5-second 256p video in just 2 seconds on a single H100.
/video/text-to-videodaVinci MagiHuman Text to Video Gallery
Experience the cinematic power of daVinci MagiHuman text-to-video generation. Create stunning videos with synchronized audio from detailed text descriptions, featuring industry-leading lip sync across 7 languages.
Rainy Tokyo Night
A woman in a red coat walks through a neon-lit Tokyo alley on a rainy night with shimmering reflections.
“Rainy night in a neon-lit Tokyo alley, a woman in a red coat walks slowly under an umbrella. Reflections shimmer on wet cobblestones. Handheld camera follows her from behind, bokeh street lights, cinematic color grade, moody atmosphere.”
daVinci MagiHuman Image to Video Gallery
Transform your static images into dynamic videos with daVinci MagiHuman. Experience seamless image-to-video conversion with realistic facial expressions, natural body motion, and synchronized lip-synced audio.
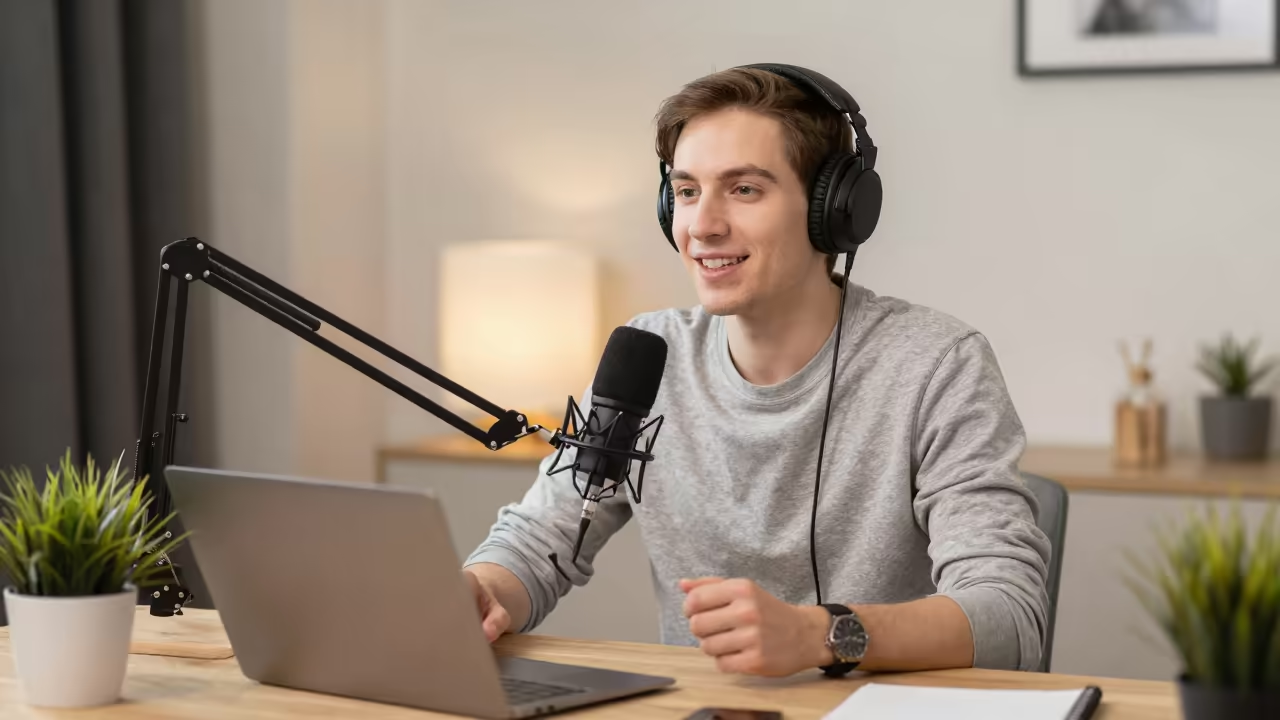
Podcast Host Speaking
daVinci MagiHuman YouTube Videos
Watch community demonstrations and reviews showcasing daVinci MagiHuman's audio-video generation capabilities
- daVinci-MagiHuman: Fast Audio-Video Synthesis - AI Research Roundup
- 达芬奇最新开源模型,革命Seedance2.0 DaVinci-MagiHuman:开源音视频生成新标杆,5秒视频2秒出,还能说6种语言! - XIAOXIAO LI
- LTX 2.3, Veo и Sora больше не нужны? Тестируем daVinci-MagiHuman - ServerFlow AI Lab - R&D в области ИИ и LLM
- Ai动画224-化繁为简!daVinci-MagiHuman,快速音视频生成基础模型的单流架构,支持多国语言,音画同步,音色参考-T8 Comfyui教程 - T8star-Aix
daVinci MagiHuman YouTube Videos
Watch community demonstrations and reviews showcasing daVinci MagiHuman's audio-video generation capabilities
daVinci MagiHuman Popular Reviews on X
See what people are saying about daVinci MagiHuman on X (Twitter)
What's daVinci MagiHuman
Sand.ai's 15B open-source audio-video foundation model with best-in-class lip sync
- · 0115BParameters
- · 021080pMax Resolution
- · 037Languages Supported
- · 042s256p Generation Speed
daVinci MagiHuman is a 15-billion parameter single-stream Transformer that jointly generates synchronized video and audio from text or images, achieving industry-leading lip sync accuracy with a 14.6% word error rate across 7 languages.
daVinci MagiHuman's Powerful Features
Discover the advanced capabilities that make daVinci MagiHuman exceptional for audio-video generation
- Feature 01 / 08
Joint Audio-Video Generation
Generate synchronized video and audio in a single pass using a unified single-stream Transformer architecture with self-attention only, eliminating the need for separate audio pipelines.
- Feature 02 / 08
Industry-Leading Lip Sync
Achieve 14.6% word error rate for lip synchronization, significantly outperforming competitors like Ovi 1.1 (40.45%) and LTX 2.3 (19.23%) in speech accuracy benchmarks.
- Feature 03 / 08
7-Language Speech Support
Generate speech-synchronized videos in English, Chinese (Mandarin and Cantonese), Japanese, Korean, German, and French with natural pronunciation and lip movements.
- Feature 04 / 08
Ultra-Fast Generation
Produce a 5-second 256p video in just 2 seconds on a single H100 GPU. 8-step DMD-2 distillation eliminates the need for classifier-free guidance without quality loss.
- Feature 05 / 08
Dual Input Modes
Create videos from text prompts or animate still images. Both text-to-video and image-to-video modes support configurable aspect ratios, resolutions, and durations from 5 to 10 seconds.
- Feature 06 / 08
Up to 1080p Super-Resolution
Generate videos at 256p, 540p, 720p, or 1080p through a latent-space super-resolution pipeline that upscales without extra VAE decode-encode overhead for efficient high-res output.
- Feature 07 / 08
Open Source Apache 2.0
Fully open-sourced under Apache 2.0 license with complete stack including base weights, distilled model, super-resolution model, and inference code for unrestricted commercial use.
- Feature 08 / 08
Human-Centric Excellence
Specialized in digital human generation with expressive facial performance, realistic body motion, and consistent character preservation across frames for professional talking-head content.
Frequently Asked Questions
Common questions about daVinci MagiHuman audio-video generation
Still have questions?
How to Use daVinci MagiHuman Text to Video
Generate videos with synchronized audio from text descriptions
Write Your Prompt
Enter a detailed description of the video you want to create. Include subject, action, speech content, and desired language for best lip-synced results.
How to Use daVinci MagiHuman Image to Video
Animate still images into videos with synchronized audio
Upload Your Image
Upload a reference image of the person or scene you want to animate. daVinci MagiHuman excels at human-centric content with realistic facial expressions and body motion.
Flexible AI Pricing
Pay-as-you-go credits or subscription plans. No hidden fees, cancel anytime.
One Time supports crypto payment (BTC, USDT, ETH, 350+)
Monthly billing